Recognize supported printed text
OCR analyzes scanned page images and attempts to identify printed English characters with the recognition model included in the tool.
Run optical character recognition on supported scanned or image-based PDF pages to make recognized text searchable. OCR results depend on language support, scan quality, resolution, rotation, and document layout.
or drop the file here
Up to 50 MiB per PDFUse OCR PDF when a PDF looks like text but behaves like an image. Recognition adds a searchable text layer only where the OCR engine can identify the printed content.
OCR analyzes scanned page images and attempts to identify printed English characters with the recognition model included in the tool.
The tool rebuilds each visible page as a JPEG image and adds recognized English text for search and selection.
Names, numbers, tables, handwriting, faint scans, unusual fonts, and skewed pages can be misread. Important text should be checked manually.
OCR PDF is useful when a scan contains printed text but no selectable text layer. It does not guarantee perfect recognition or recreate every layout as editable document content.
Choose the scanned PDF, process the pages, then download and open the result to verify the recognized text before relying on it.
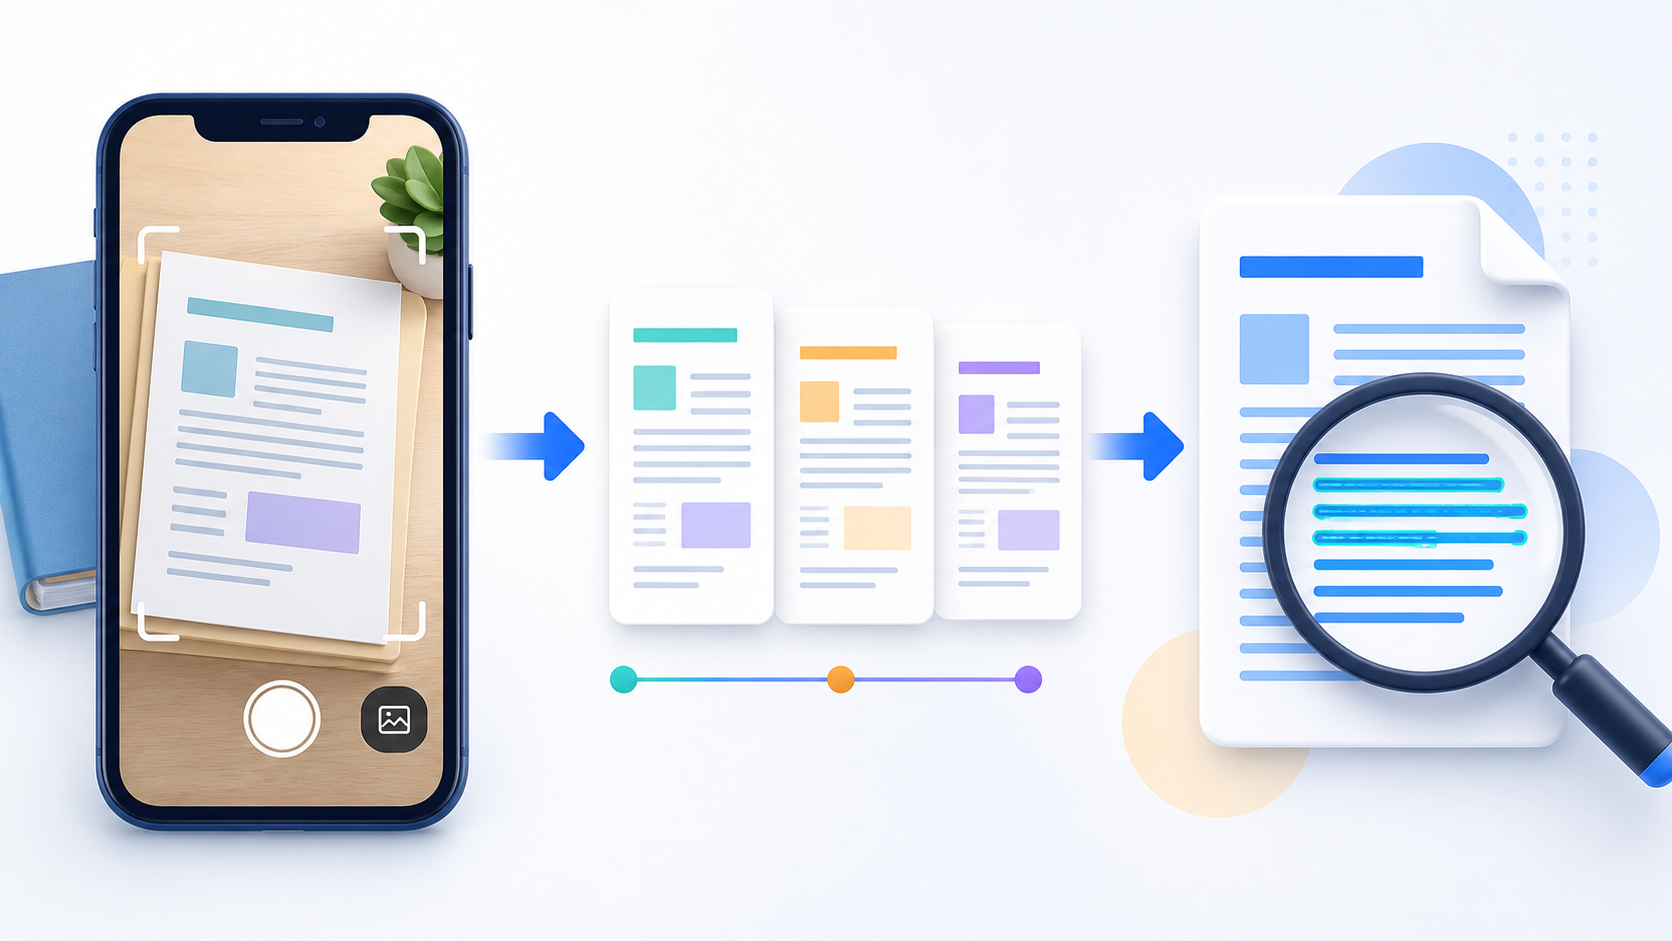
Optical character recognition analyzes page images and attempts to identify characters so recognized text can become searchable or extractable.
PDFKaka OCR currently supports English printed text.
The current OCR workflow is intended for printed English text, not handwriting.
No. Accuracy depends on scan quality, resolution, rotation, language, fonts, layout, and the content itself. Review important text manually.
OCR rebuilds each page as a JPEG image and adds a searchable text layer. The original page image bytes are not preserved unchanged.
No. Selected PDF contents are processed locally in this browser; OCR assets are loaded from PDFKaka only when recognition starts.