PDF to text guide
How to remove repeated headers and footers from PDF text
Extract the text first, then review and remove recurring page labels without deleting similar wording from the document body.
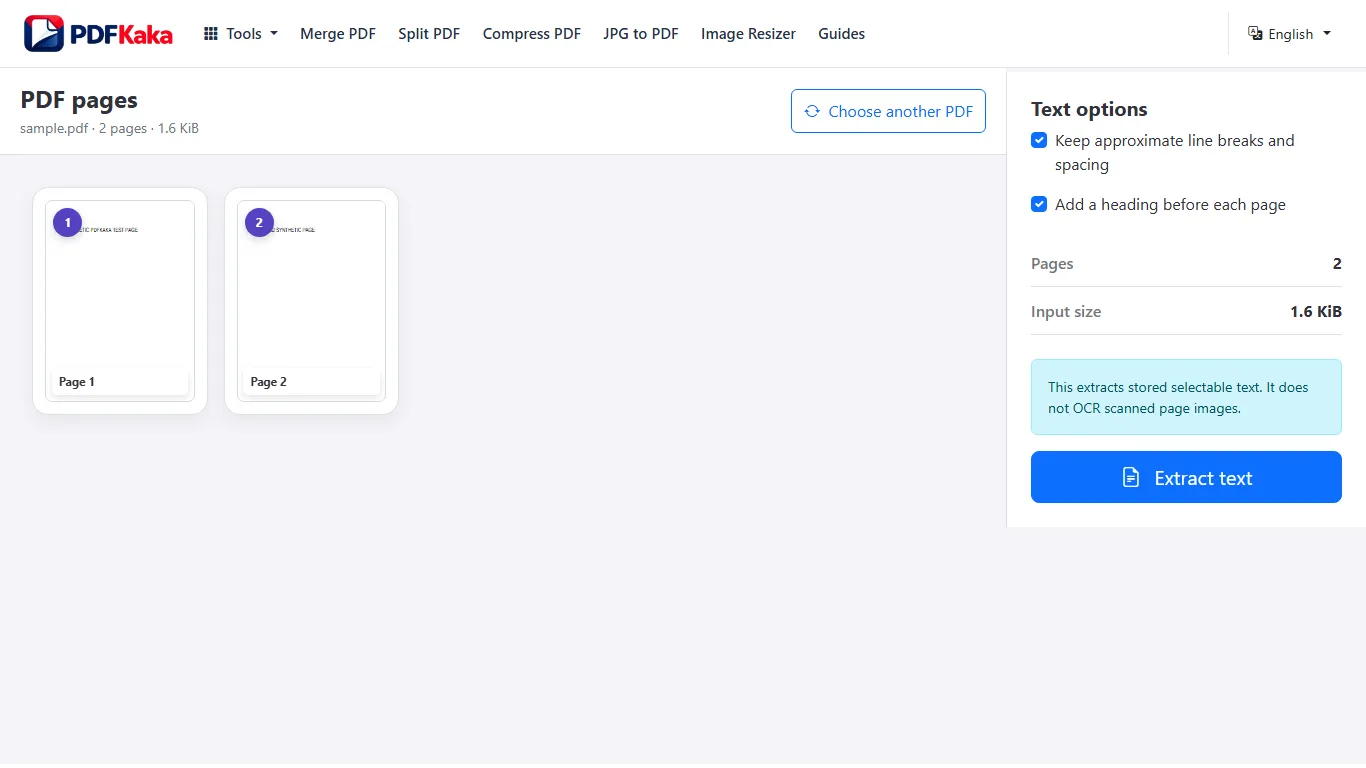
Extract the PDF text
- Search the TXT file for each repeated header or footer and compare every removal with the PDF.
- Choose a PDF that already contains selectable text.
- Choose whether approximate spacing and page headings should be included.
Text extraction does not replace OCR
Extracts stored selectable text only; no OCR and no page images.
FAQ
Does PDF to Text run OCR on scanned pages?
No. PDF to Text extracts text that already exists in the PDF. Use OCR PDF first for image-only scans.
What is the current input limit for PDF to Text?
PDF; One PDF ≤50 MiB, ≤500 pages; ≤1,000,000 extracted characters.
What does PDF to Text create?
stored selectable text only, no OCR; TXT ≤150 MiB.