Redact PDF guide
How PDFKaka Redacts Selectable PDF Text
Search exact selectable text and rebuild matching page content with the detected text covered rather than drawing a removable annotation.
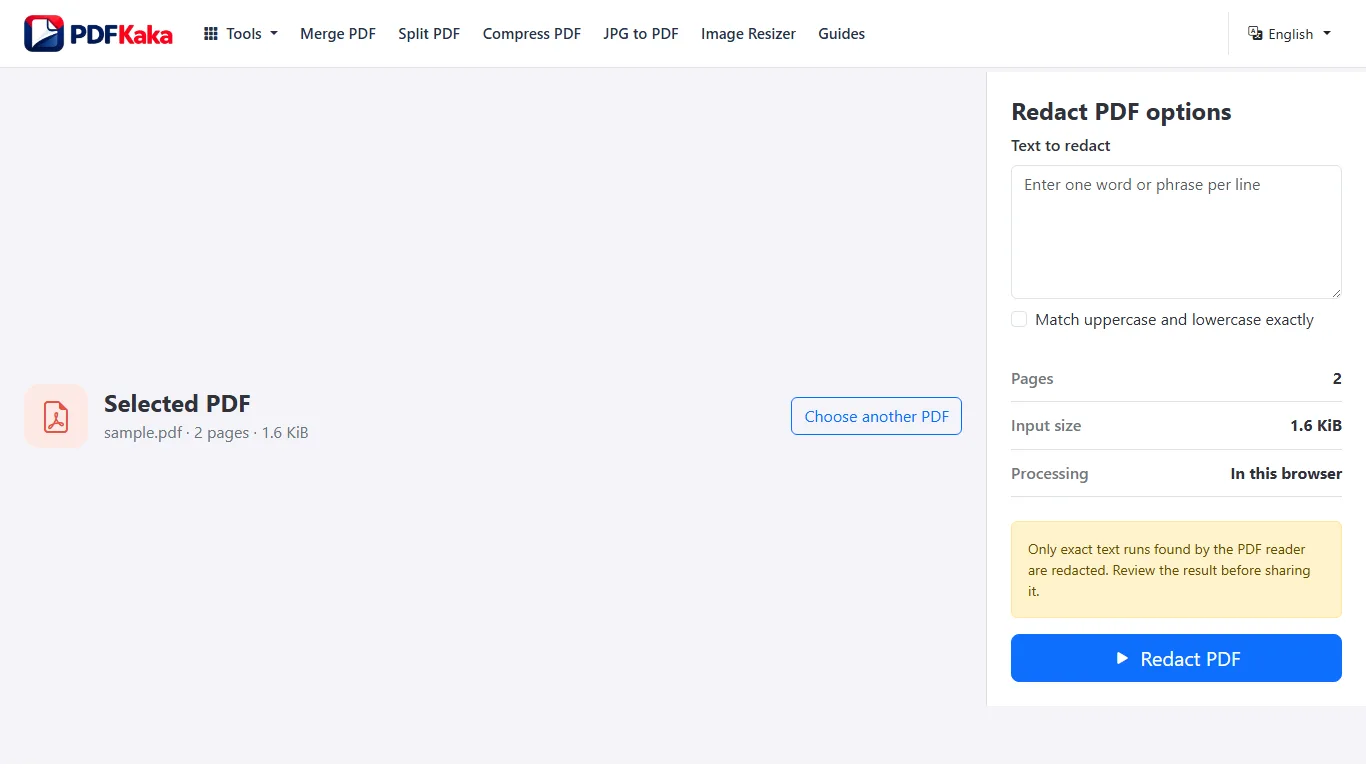
Apply the supported text redactions
- Choose a PDF containing selectable text and enter each literal term on its own line.
- Search for the original terms, attempt text selection, and visually inspect every match before sharing.
- Choose whether matching should respect uppercase and lowercase.
What text-based redaction can and cannot match
Literal substring matching within individual text runs; no OCR, arbitrary boxes, cross-run matching, or match preview. Output pages are rasterized.
FAQ
Can Redact PDF find text inside a scanned image?
No. The current Redact PDF workflow does not perform OCR. A scan must first contain suitable selectable text for text-based matching to work.
What is the current input limit for Redact PDF?
PDF; One PDF ≤50 MiB, ≤100 pages, render cap 20 MP/page.
What does Redact PDF create?
matched pages are rebuilt as images, so selectable text/features can be lost; One PDF ≤150 MiB.