PDF to Markdown guide
How to handle PDF tables and images in Markdown
Treat extracted text as a draft because complex tables, captions, figures, and image relationships do not automatically become complete Markdown.
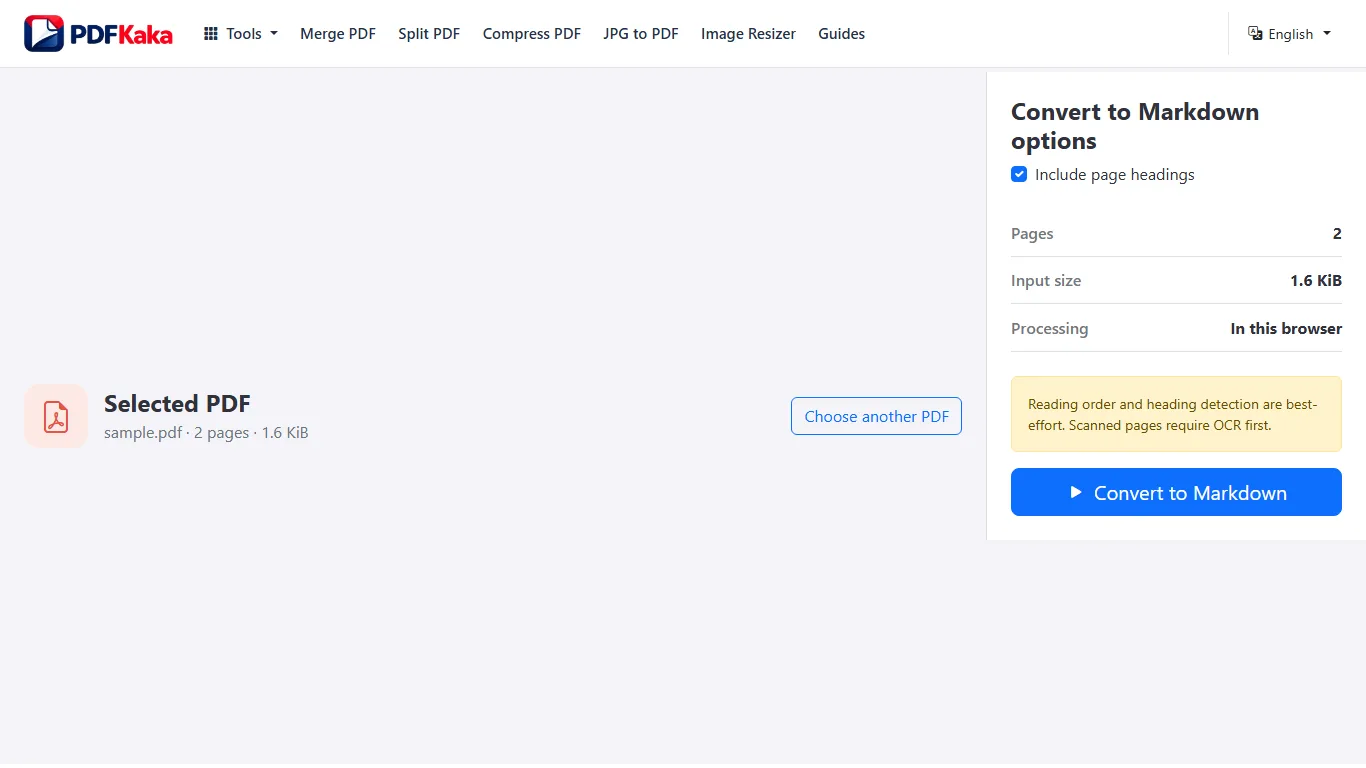
Convert the PDF to Markdown
- Rebuild important tables and add image descriptions or references after comparing them with the PDF.
- Convert the stored text into the tool's best-effort headings and paragraphs.
- Choose a PDF that contains selectable text, or prepare a reviewed OCR result first.
Text extraction versus OCR for scanned pages
No OCR. Uses selectable text and a heading heuristic; does not reconstruct lists, tables, images, links, or columns.
FAQ
Does PDF to Markdown OCR scanned pages?
No. Use OCR PDF first when a scanned document does not already contain usable selectable text.
What is the current input limit for PDF to Markdown?
PDF; One PDF ≤50 MiB, ≤100 pages; ≤1,000,000 extracted characters.
What does PDF to Markdown create?
selectable text extraction, best-effort reading order; no OCR; Markdown ≤150 MiB.