PDF to Markdown guide
How to convert a scanned PDF to Markdown using OCR
Markdown conversion needs readable text objects; a scanned PDF normally contains only page images.
On this page
Recognize the scan before Markdown conversion
Open the image-only document in OCR PDF. Keep the job within the 25-page OCR limit, then search the result and compare important passages with the page images. Correct source quality problems before moving on.
Convert the reviewed OCR result
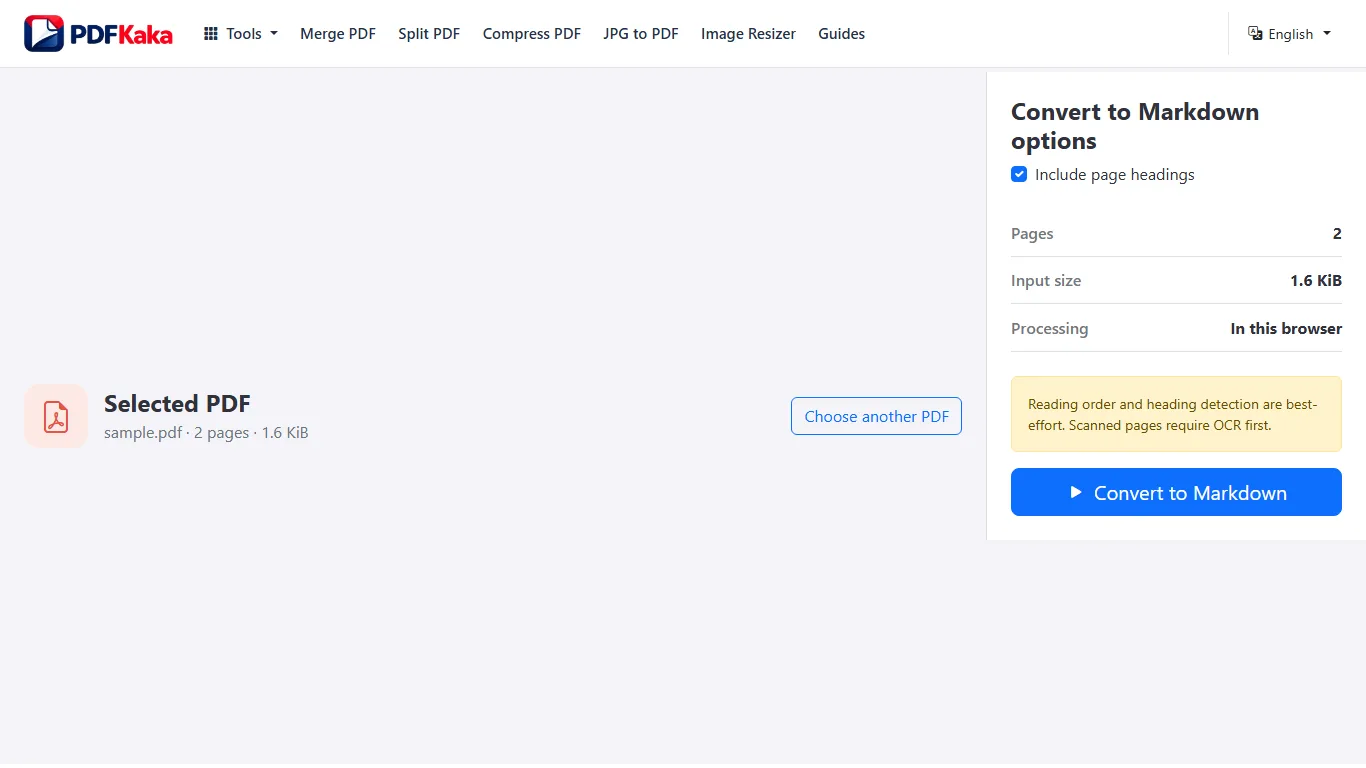
Open the searchable PDF in PDF to Markdown. The converter uses existing text and applies best-effort heading and paragraph rules. It does not reconstruct every table, image, or visual layout.
Repair structure in the Markdown
Check heading levels, paragraph order, lists, table content, and repeated headers. OCR errors can become Markdown structure errors, so correct recognition mistakes before relying on the file for documentation or an AI workflow.
Check the OCR text before judging the Markdown
Search the OCR result for a few phrases from different pages before conversion. Names, figures, punctuation, column order, and headings deserve separate checks because a plausible-looking Markdown file can still contain recognition or reading-order errors. Keep the searchable PDF beside the Markdown while correcting the structure.
FAQ
Can PDF to Markdown run OCR on a scanned PDF?
No. Use OCR PDF first, review the searchable result, and then send that PDF to PDF to Markdown.
Why do OCR mistakes affect Markdown headings?
The Markdown converter interprets recognized text and layout clues. A misread heading can therefore become an ordinary paragraph or an incorrect heading level.
Will scanned tables become Markdown tables automatically?
Do not expect reliable table reconstruction. Review the extracted text and rebuild tables manually when structure matters.