HTML to PDF guide
What Formatting PDFKaka Preserves from HTML
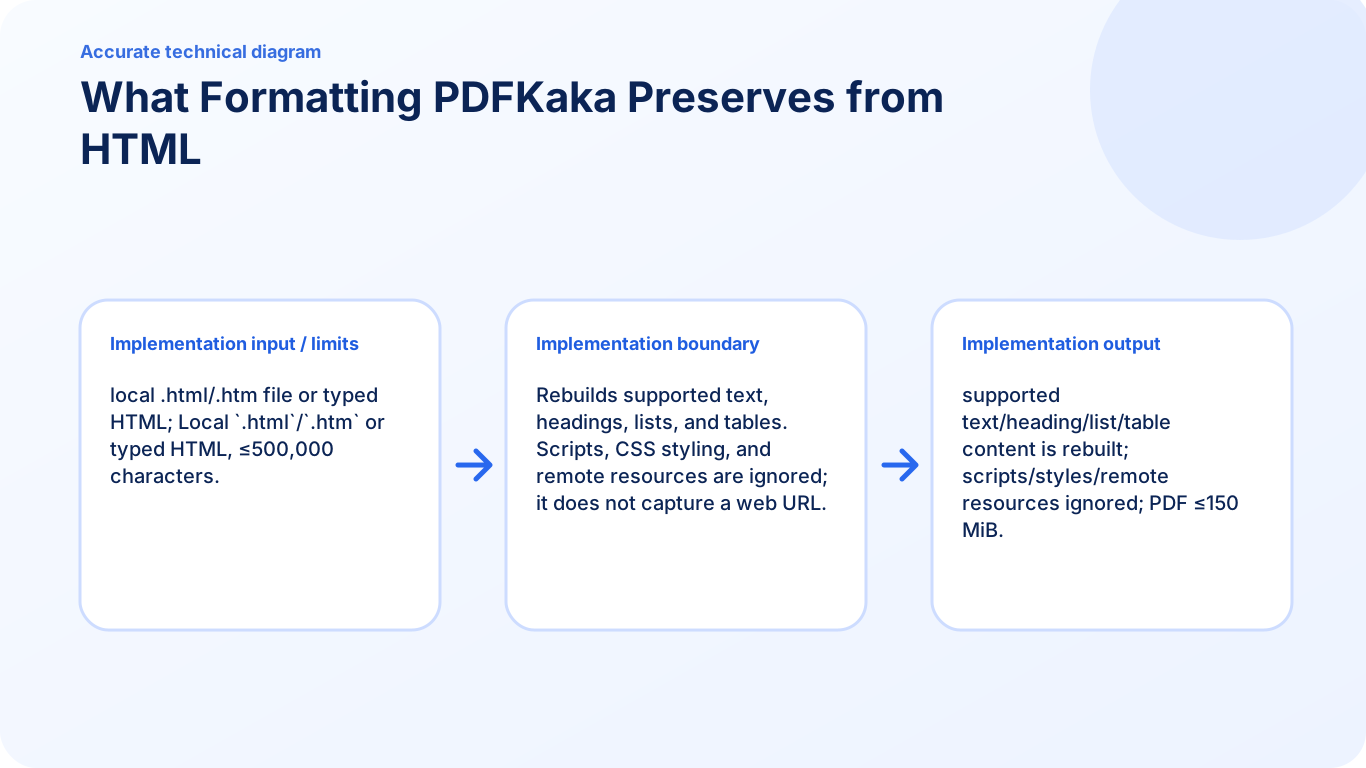
HTML can contain semantic structure, visual CSS, scripts, and remote assets, but the current PDFKaka converter does not preserve all four categories.
On this page
Content the converter rebuilds
Supported paragraphs, headings, lists, and tables provide the main document structure. Use self-contained HTML whose meaning remains clear without a stylesheet. The resulting PDF is a newly built document rather than a browser print of the original page.
Formatting that does not carry across
Do not rely on CSS for fonts, colours, spacing, positioning, responsive layout, or print-specific page rules. JavaScript does not run, and remote stylesheets or images are not loaded. Forms and embedded pages are also excluded from the safe conversion path.
Prepare HTML for a predictable result
Use headings for hierarchy, paragraphs for prose, lists for sequences, and simple tables for tabular data. Replace information conveyed only by colour, background images, or generated content with visible text. Keep every required item inside the supplied HTML rather than depending on an external URL.
Compare structure instead of pixel fidelity
After conversion, compare the order and wording of headings, paragraphs, list items, and table cells. Review every page boundary and look for missing information that existed only in CSS or a remote asset. If exact web-page appearance is required, the current converter is not the appropriate capture method.
FAQ
Will the PDF use my CSS fonts, colours, and spacing?
No. CSS styling is ignored in the current conversion path.
Are remote images or stylesheets loaded?
No. Required content must be self-contained because remote resources are not fetched.
What HTML structure is most useful to preserve?
Use supported headings, paragraphs, lists, and simple tables, then check their reading order and page flow in the PDF.